 arkana
Understanding AI: Linear Models
DRAFT
Thanks to the previous two articles, our mental model to understand the moving parts of ML should be more or less established: vectors and linear algebra for representation purposes, probability and statistics as the framework behind naturally uncertain data, and optimization as the technique that ultimately allows us to flesh out good predictors.
But we've been working at a very high level, without really applying most of the concepts we've discussed so far. So how about we take a stab at seeing them in action?

To really kick off our journey then, we'll begin by looking at arguably the simplest kind of predictors we can find: linear models!
Remember that, as we discussed a couple articles back, there's a wide range of models we could choose from, ranging from very plain and simple ones, to very sophisticated and complex. Choosing the right model for the task at hand is our first challenge!
And I say models (plural), because during today's exploration, we'll be touching on a couple different kinds of predictors that, while both linear in nature, are tailored for very different purposes.
Sounds like a plan then! Where do we start?
Linear Regression
Our first mission will be very simple: we'll try to fit some data to a plain ol' line.
I know, I know - you're here for all the AI goodness, and here I am, trying to draw a line through some points.
Like, what the hell Frank.
Before you abandon ship though, let me just say this: linear regression has a lot to teach us about things that we'll be using even in the most complex of settings. And despite its apparent simplicity, there are entire books (like this one or this one, for instance) solely dedicated to analyzing this humble model. Yeah. It's a much deeper topic than one would initially imagine.
Assuming you're still there (I hope so!), let's start by trying to frame our problem first, and then we'll see how we handle ourselves around it.
Drawing Lines
Back in my days as a chemical engineer, linear regression was a tool we used quite a lot, without ever using the machine learning branding. As it turns out, many observations about the physical world are either simple linear relations, or can be cleverly manipulated to behave as such. So the simple act of drawing lines became a powerful tool for analysis, and has allowed scientists throughout history to pinpoint physical constants and validate physical laws.
It's pretty powerful, I'd say.
Rather than drawing these lines by eye though, we'd like to apply the things we learned in the previous article. And for that, we first need to ask ourselves: what is a line?
In its simplest interpretation possible, a line is just a function with this form:
As you can see, this little expression has only two knobs we can turn.
The first one is usually called the slope , and controls how steep the line is. The bigger the slope, the faster the output will grow (or shrink) as we move the variable . The second one, normally called the intercept, controls where the line sits vertically on a plane. It's the value we get when is exactly zero, so it officiates as our "starting point" of sorts.
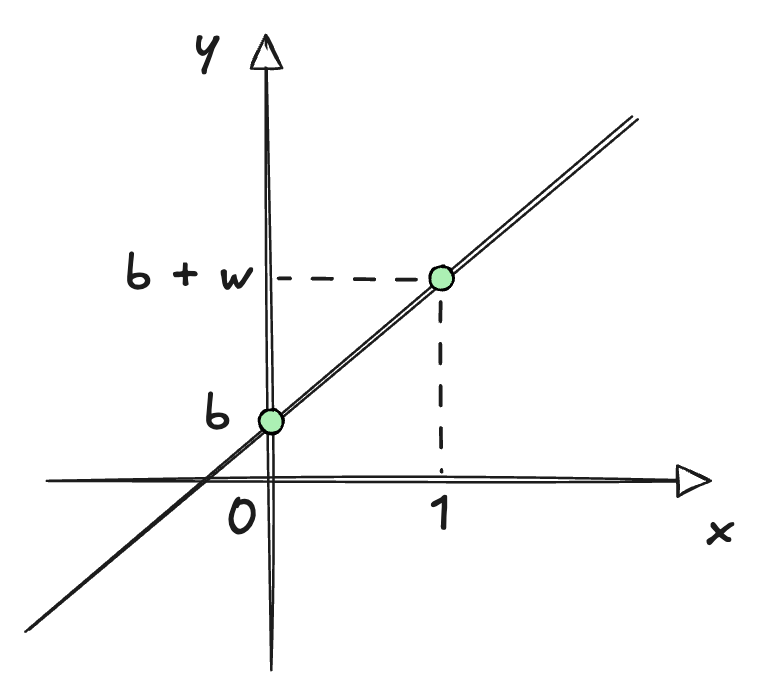
Now, naming conventions are not always the most obvious in math, and we sometimes use weird letters to represent quantities. Even then, the choice of and for the slope and intercept in this case is not a decision made on a whim, but in fact quite deliberate.
There's good reason behind this, for in the world of Machine Learning, these two quantities receive special names. You might have already guessed the , since we've already talked about this: we call it the weight, and it directly affects how sensitive our model is to changes in the variable .
The other one, we call the bias , and it's exactly that: how skewed or biased our model is when weights don't matter, meaning the value of is either 0 or close to it.
You could think of this as the default value of the model! And mathematically speaking, this is the knob that allows us to avoid having the line go through the origin .
These names will follow us for the rest of the series, so using and is a good reminder of what these thingies mean. When we get to fancy things like neural networks, we'll find that they're really just a whole lot of weights and biases stacked together and transformed in convoluted ways. So getting acquainted with them early will pay off big time later!
Lastly, there's one extra piece of notation worth introducing before we move on. Our simple line spits out a prediction, and as you might remember from our discussion about uncertainty, a prediction is just a guess. To make this very clear, we'll assign a special notation to our prediction:
And we'll reserve the notation for the actual observed value (the one we'll try to match as best as possible).
With that, we have our model, a humble little line. But we haven't said anything about the specific values of and . After all, there are infinitely many lines to choose from, each with its own parameters.
Obviously, we're interested in a single line, the one that best fits our data. Which begs the question: how do we find it?
The Loss Function
In our previous encounter, we've already talked about how the usual process goes. Since we now have an actual model, the next step is to choose a suitable loss function, and minimize its value by adjusting the model's parameters ( and ).
But... how do we know what a suitable loss function is?
It's a tricky question. A loss function must measure how wrong the prediction is, but the thing is there's also infinitely many ways to go about this!
I guess a good start would be to make it as intuitive as possible! Probably the simplest way we could measure "wrongness" is by calculating an error for each prediction, and then just adding those errors up. Something like:
And then just:
Looks fine, right? Think again! There's in fact a big problem with this loss function. Can you spot it?
The problem is that the sign of the errors matter. Some errors might be positive, and some might be negative, so they could balance out even when a simple visual inspection would tell us this makes no sense! For example:
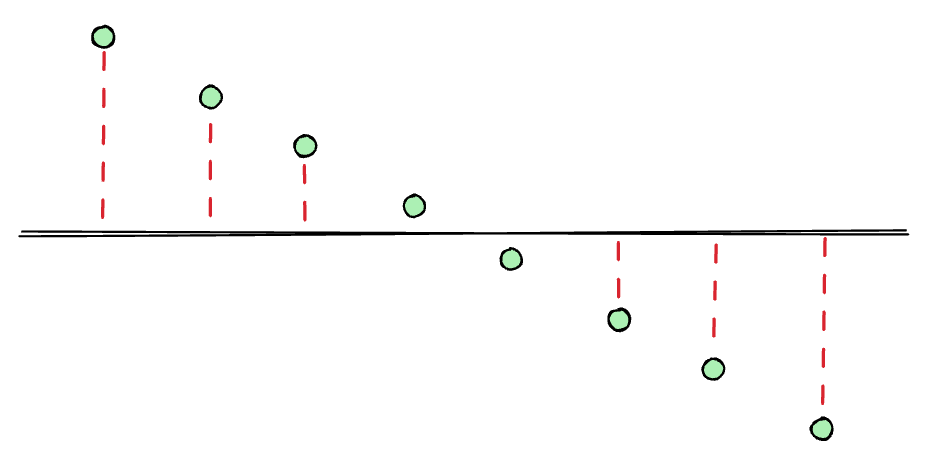
This loss function won't do - but maybe we can refine it a bit more. All we need to do is find a way for the errors to never cancel out, and we should be good. And while there are also many ways to do this, one strategy reigns supreme in this area: squaring the errors!
By doing this, all the terms will be positive, so the loss function will always take non-negative values, as the errors will never cancel out. This is called the mean square error (or MSE for short), and will be our loss function of choice.
This is actually the most commonly used loss function! And there are several reasons why this is the case.
Again, I don't want to deviate too much into those explanations to not lose focus, but I do want to share a video that provides yet another perspective of why choosing MSE makes sense!
Finding the Best Fit
Loss function, check! Naturally, the next step is to find the parameters and that produce the best fit, meaning that they minimize the loss function.
With this model, it's actually possible to do something we'll almost never be able to do: finding a closed form solution for the best parameters. As you already know, this is done by way of optimizing the loss function, which means finding the minimum.
And do you remember the slope of a multidimensional hill we talked about last time? A minimum (or a maximum) will sit at a point where there's exactly no slope, so that gives us a set of conditions that a minimum should satisfy:
After we calculate the derivatives and simplify a bit, we end up with:
A system of two equations for two unknowns ( and ), so if my high school memories serve me right, we should be able to solve this! From this point on, it's just a little more algebra (I'm gonna conveniently skip in the interest of keeping this digestible), and we arrive at the closed-form results we're looking for.
For simplicity, we need to introduce the average of all values as , and likewise for the values.
Voilà! Those are the optimal and ! Piece of cake, right?
While we don't need to worry about analyzing these results too much now, I'm gonna say a couple things for those of you who might be interested in a bit more, because there's a lot to unpack even for such a simple model.
If you happen to have a little more context on probability, notice that is really just the covariance between and , divided by the variance of . That means is a measure of how much tends to move together with , scaled by how spread out is. And simply anchors the line so it passes through , sort of the "center of mass" of our data.
We'll talk more about variance and covariance in due time, but the ideas are simple enough they allow us to make some sense out of the result!
While this can be done fairly easily with a few operations from linear algebra (namely a couple matrix multiplications), I think it's fair to say this whole process is a bit tedious. And things will only escalate from this point onwards... so do we really have to go through such a painstaking process every time?
We'll answer that by using our little formulas to "train" our first model. Shall we put it to the test?
A Worked Example
I'm just gonna say this now: I don't like Python. I really just don't feel it. You know who likes it though? The entire freaking ML and AI industry!
Like, seriously, everyone and their mother seems to be using.
All this to say: the examples we'll be working through along the way will all be in Python. And you'll ask you in advance to excuse my non-fluency in the language. You can probably do it cleaner and better - just bear in mind these are just examples.
Okay then! Let's start by generating a few points around a line:
import numpy as np

rng = np.random.default_rng(42)

n = 40
true_w, true_b = 2.5, 1.0

x = rng.uniform(0, 10, n)
y = true_w * x + true_b + rng.normal(0, 2, n)
Nothing fancy: we're just picking a "true" line (, ) and generating some points around it, with a bit of random noise thrown in to make things a little more realistic. If we plot these points, here's what we get:
import matplotlib.pyplot as plt

# Generate x, y

plt.scatter(x, y)
plt.xlabel("x")
plt.ylabel("y")
plt.show()
You'll get something like this:
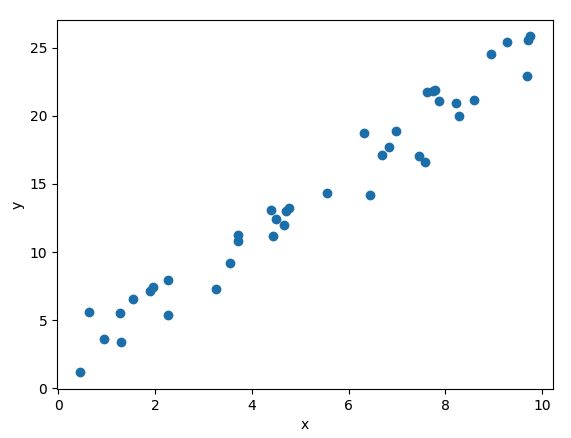
A nice, noisy cloud of points, showing a clear linear trend. Now, let's put those closed-form formulas we derived earlier to work, and see if we can recover something close to our original line:
# Generate x, y

x_mean, y_mean = x.mean(), y.mean()

w = np.sum((x - x_mean) * (y - y_mean)) / np.sum((x - x_mean) ** 2)
b = y_mean - w * x_mean

print(f"w = {w:.2f}, b = {b:.2f}")

y_true = true_w * x + true_b
y_pred = w * x + b

plt.scatter(x, y, label="data")
plt.plot(x, y_true, color="green", linestyle="--", label="true line")
plt.plot(x, y_pred, color="red", label="fitted line")
plt.xlabel("x")
plt.ylabel("y")
plt.legend()
plt.show()
And you'll see something along these lines (no pun intended):
Pretty close, right? Sure, it's not a perfect match, but it's close enough. It's reasonable to say our little formula has done its job.
But there's an important lesson to take away from this: even with our exact formula for the optimal solution, we don't recover the real model. We never really do, because as we've mentioned many times already, real data is noisy.
So to answer the question from before: do we really need to find those closed-form formulas for the optimal solution to the loss function we're using? Not really! There are other, simpler ways to get to a good enough solution - and if we do that carefully, good enough might as well be as close to reality as the actual optimal solution, because the latter isn't perfect anyway!
In short: since we're always dealing with imprecise data, "good enough" is probably okay.
Wonderful! We've officially "trained" our very first model. Not bad, eh?
And believe it or not, this simple trick is put to work absolutely everywhere out in the wild. Economists use it to estimate how spending affects growth. Doctors use it to relate dosage to blood pressure. Real estate sites use it to guess a house's price from its size and location. Any time there's a rough "as goes up, tends to go up (or down) too" kind of relationship lurking in some data, there's a good chance a straight line is quietly doing the heavy lifting behind the scenes.
And trust me, there a lot more to say about this model, innocent as it may look. We may be interested, for example, in ways to measure how well our prediction matches the data. Or even better, we may want to understand if the model itself is the correct one. Just look at the next image - would you say a line is the correct predictor for these points?
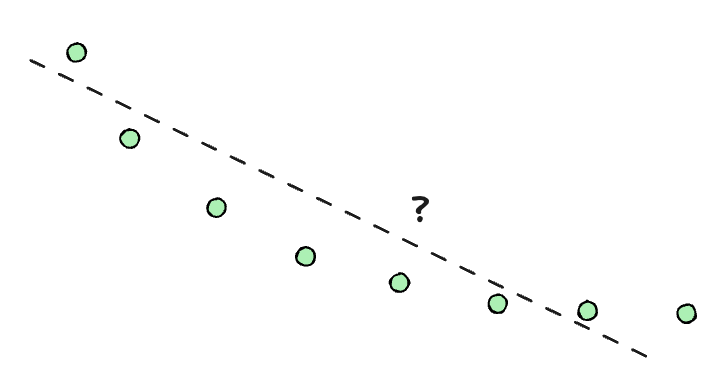
Lots of questions for sure. It's a hugely helpful model for a number of applications, but you probably already see it has limitations and it's definitely not a silver bullet. And while there are clever ways to navigate all those situations I described (for example, the image from before can be transformed pretty easily), I want us to switch gears and focus on an entire class of problems it's not even designed to solve.
Remember our recommendations engine from the start of the series? Let's talk about that.
A Different Question
If you recall, back then we wanted to use our engine to show Alice some movies she might like.
Our regression model from before is a little awkward in this context. It's designed to spit out a continuous output: a number that can take any value along a certain range, depending on the we feed the model.
Suppose we do have such a line to predict which rating Alice would give a movie. Does that mean that a is a movie she'd like? What about a ? Maybe that's a good enough rating for her! Who knows!
And therein lies the problem: our regression model answers a different kind of question. We need a different model that answers something much more humble: a simple yes or no.
This is a different problem to tackle, called classification, which deals with discrete outputs: a small, fixed set of categories to choose from.
Which in our case, is just yes/no, or like/dislike, or maybe even /!
It seems drawing a line won't help in this situation.
...Or will it?
With a little twist in perspective, it just might!
Drawing a Boundary
Let's say we're looking at just two features for now: a movie's runtime, and its average rating from other viewers. Every movie Alice has watched becomes a point on a 2D plane, colored by whether she liked it (blue points) or not (red points):
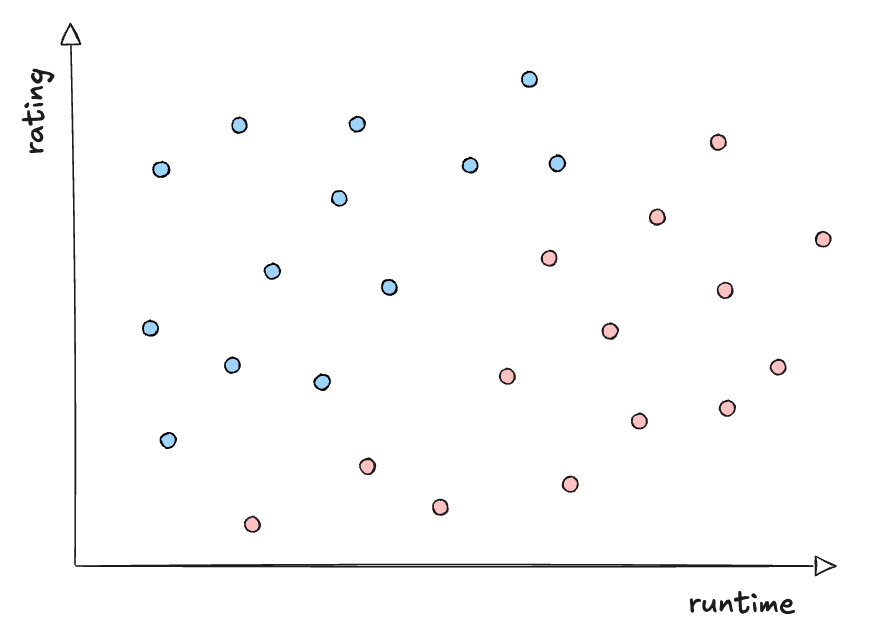
The two sets of points are reasonably well separated in this example. There seems to be a clear pattern... almost as if... wait a second:
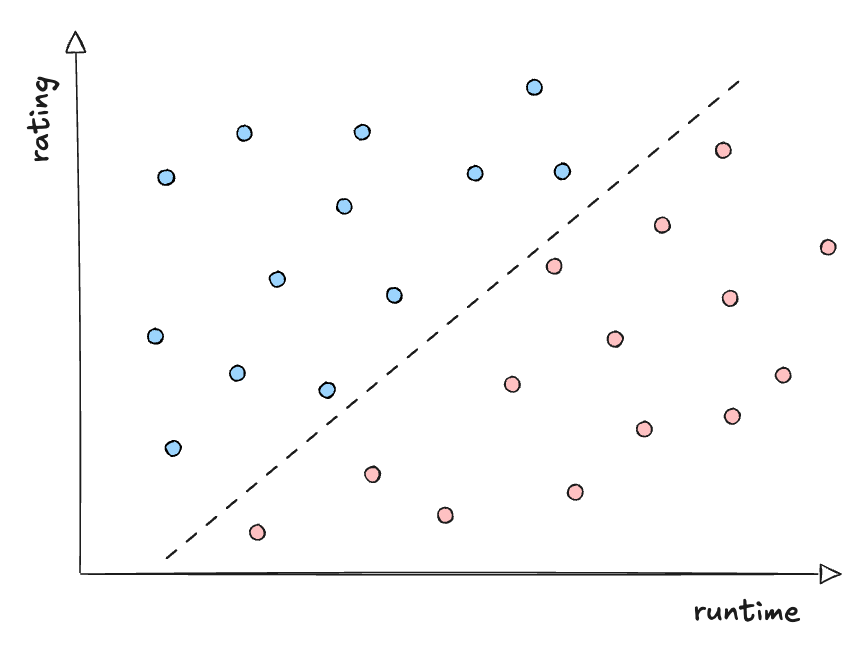
Clear as day, we can draw a dividing line! This is what we call a decision boundary: a boundary that separates one class from the other.
Admittedly, drawing this line is a little more involved than before, and we'd have to lean on a classic algorithm called Support Vector Machines (SVMs), which seeks the best possible line so that it leaves the widest possible margin between the two classes.
Actually finding this optimal margin is gonna be a rabbit hole for another day though!
In two dimensions, this separation looks like a simple straight line; if we push things into higher dimensions, the decision boundary will become a hyperplane, but the core idea never changes.
And this simple trick - splitting a space in two with a straight line - turns out to be surprisingly useful out there in the real world. Spam filters, credit approvals, medical screenings, fraud detection... an awful lot of everyday yes/no decisions boil down to finding the right dividing line between two groups of points, exactly like the one we just drew for Alice's movie taste.
Cool, isn't it?
Summary
Quite a lot of things to say about a humble bunch o' lines, right?
Importantly, we saw our first proper model in action, linear regression. It was a great exercise in problem framing, loss function selection (for which we used the mean squared error, after ruling out the naive sum of errors), and even found a closed-form solution for the best possible weight and bias!
Then, with a small adjustment in our framing, we repurposed that very same idea (carefully drawing a line) into a decision boundary, and used it to tackle an entirely different kind of problem: classification.
Both linear models, but used very differently. And generally speaking, these two types of problems will cover a great deal of the more advanced machine learning techniques we'll learn along the way, just that they will be reframed and used in new and interesting ways.
Remember, this is all about building the foundations. We'll get to the cooler stuff once we've cleared the basics!
Before we close this article though, I want to talk about our little boundary trick a little further, since it has some rough edges we just can't ignore.
For one, a "yes or no" answer is really all about confidence. Would you say a point sitting just barely on the "yes" side of the boundary should get treated exactly the same as one sitting miles away from it? Doesn't feel quite right, huh? Intuitively, we should be more confident about the second one than the first!
Wouldn't it be cool if our model could output something like a probability? Say, a number between and that tells us not just the answer, but how confident we are about it!
Turns out there is indeed a neat little function that does exactly that! It's called the sigmoid function, and it will be the subject of further analysis in upcoming articles!
And then there's an even deeper question underneath all these boundary delimitation shenanigans: why should we use a straight line to separate our classes to begin with? I mean, it's just a line - and contrary to the regression case where we had a weight and a bias that carried some meaning, a line separating Alice's tastes in movies will be a little harder to interpret.
So what if we flipped the question around entirely? Rather than asking "where's the line that best separates these points," we could instead ask: given a new point, which class was it more likely to have come from?
That's a fundamentally different way of thinking about classification - one that leans on probability, rather than geometry. And it's exactly where we're headed next.
See you soon!
Did you find this content useful?
Support Frank Mangone by sending a coffee. All proceeds go directly to the author.